
Most dedicated server buyers start with a catalog page. They pick a processor tier, choose a RAM configuration, select a storage option, and submit the order. That process works well enough for workloads that fit neatly into standard templates. The friction begins when a workload does not fit — when a team needs a specific NVMe drive count that no preset offers, a custom RAM configuration for an in-memory database, or a network card that the standard build simply does not include.
What happens next is where providers reveal themselves. Some providers accommodate custom hardware requests readily, treating them as routine procurement. Others treat any deviation from the catalog as an exception that requires weeks of back-and-forth, a minimum contract commitment, or a pricing structure that bears little resemblance to the advertised tiers.
In practice, the catalogue only shows standard configurations. The sales and provisioning process determines whether a requested component is actually available, how long procurement will take and which contractual conditions apply.
Why Standard Dedicated Server Configurations Leave Some Workloads Underserved
Standard server catalogues are generally designed around repeatable configurations that providers can stock, provision and support efficiently. Specialised workloads may require resource ratios or components outside those standard configurations.
Some large in-memory databases may require more RAM per CPU core than a provider’s standard configurations offer. Determine the required ratio from measured dataset size, replication, persistence, operating-system overhead and growth projections.
Similarly, high-density NVMe storage requirements — common in video transcoding pipelines or large-scale search indexing — often exceed the physical drive bay count that a standard chassis supports. Ordering more drives than the template allows is not always a configuration option; it can require a different chassis entirely, which moves the request out of the self-service catalog and into a manual procurement process.
Specialized network interface cards represent another common gap. Standard builds typically ship with the provider's default NIC, which suits general traffic well. Teams running latency-sensitive financial applications or high-packet-rate workloads may need a specific card model — or a higher port count — that the catalog simply does not list.
GPU requirements follow a similar pattern: some providers offer GPU-equipped dedicated servers as standard products, while specific GPU models, accelerator counts or power requirements may require a custom quotation.
Understanding those limits is important. Use the provider comparison to create an initial shortlist, then confirm each provider’s custom-hardware process directly before signing a contract.
Custom requests may involve RAM expansion, additional storage, specialised networking or accelerators. The mix varies by provider and customer base.
What Custom Hardware Requests Providers Actually Receive
Custom requests can involve RAM capacity, storage layout, NIC models, processor configuration or accelerators. Their relative frequency varies by provider, customer base and available inventory.
What separates requests that move quickly from those that stall is usually not technical complexity but inventory position — a component the provider already stocks for another SKU can often be swapped in with minimal lead-time impact, whereas a NIC from a vendor outside the standard supply agreement may trigger a separate procurement process even when the chassis has an open slot waiting for it.
- RAM upgrades beyond the maximum capacity listed in the standard catalog tier
- Additional drive bays or swapped storage configurations within the existing chassis
- Specific NIC models not included in the default build
- Dual-socket CPU board configurations where the standard SKU ships single-socket
- Non-standard total memory capacities that fall between two existing catalog tiers
- Alternative processor steppings tied to a particular performance or compatibility requirement
- Network cards from vendors outside the provider's standard supply agreement
Alternative CPU socket configurations may require a different motherboard or chassis and therefore need individual feasibility confirmation.
RAM expansion may be relatively straightforward when compatible modules, motherboard capacity and supported memory channels are available. The provider must still confirm compatibility, stock and lead time. Additional NVMe drives are similarly manageable when the physical bay count allows it and stock is confirmed.
Where teams run into friction is when the request requires a different motherboard or chassis altogether: that shift moves the order from inventory fulfillment into active procurement, which introduces lead times that can range from days to several weeks depending on component availability.
Network card substitutions surface a meaningful divide between providers. Some treat NIC selection as a straightforward configuration option and maintain a short list of alternatives at their facilities. Others treat any deviation from the default card as a custom build, requiring a separate quote and a longer delivery window.
GPU configurations are more likely to require a manual quotation because model availability, chassis capacity, power and cooling requirements vary. Use the provider comparison to shortlist providers, then confirm custom-build availability directly with each shortlisted operator.
Where Providers Draw the Line on Dedicated Server Custom Hardware
Common reasons for rejecting a custom request include component availability, platform compatibility, chassis capacity, power or cooling limits, supportability, certification requirements and insufficient contract value.
A power or cooling constraint usually requires a different rack, facility or hardware design, while a temporary supply-chain constraint may be resolved through another procurement cycle.
What matters here is understanding which reason applies to a given refusal — because that determines whether a different conversation with the same provider might still produce the result you need.
Component availability can be a limiting factor, and its effect varies by provider. A temporary sourcing problem should be distinguished from a permanent power, cooling, chassis or platform constraint.
Procurement capability depends on local inventory, supplier relationships, order volume and access to OEM or distributor channels; provider size alone is not a reliable indicator.
Data center power and cooling limits create a harder boundary. A chassis designed to house four high-TDP GPUs may draw power and generate heat that exceeds what a standard rack allocation supports. Some facilities can accommodate this with a dedicated power circuit and additional cooling, but that itself requires a minimum commitment — which may include a larger rack allocation or a longer contract term — that makes a single custom build economically unattractive for the vendor.
Teams planning GPU-dense or high-core-count configurations should ask about per-rack power budgets explicitly, since this constraint rarely appears in catalog descriptions.
Minimum order thresholds represent the third boundary. A provider may require a longer term, minimum order value or customer-funded procurement when a component must be sourced specifically for one deployment.
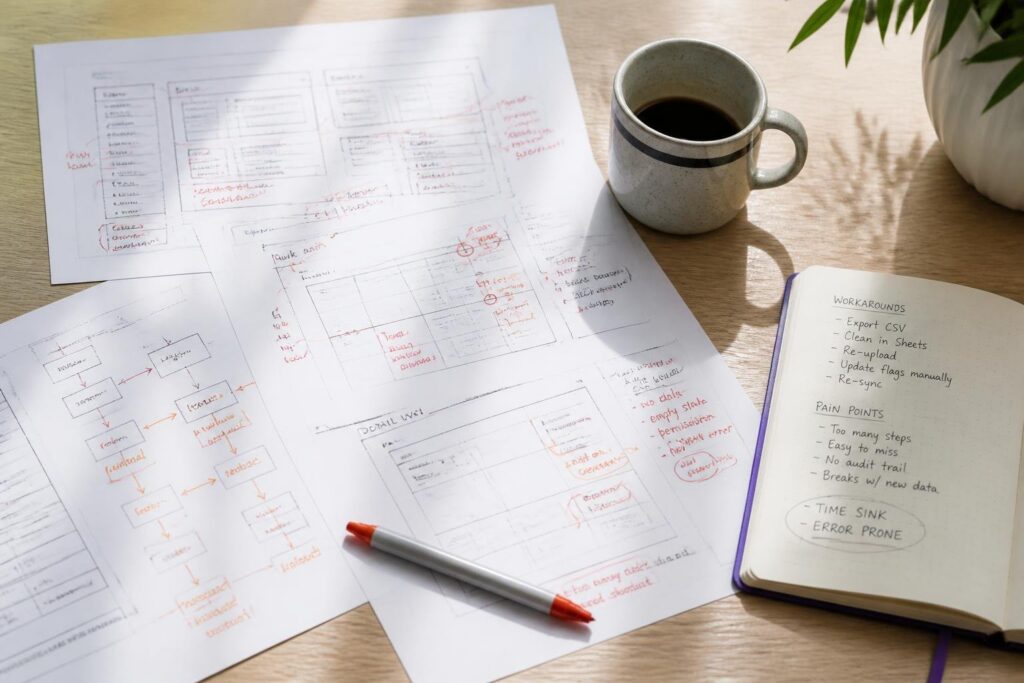
The moment a team finds itself engineering workarounds to compensate for hardware constraints rather than focusing on core development, the standard catalog has effectively stopped serving its purpose.
How Do You Know When Your Workload Has Outgrown Standard Options?
The clearest signal that a catalog server has become the wrong fit is when your team spends more time working around hardware limits than building on top of them. That inflection point rarely arrives as a single dramatic failure. It accumulates through smaller operational frictions that are easy to rationalize individually but expensive in aggregate.
Performance ceiling indicators are the most direct diagnostic. Sustained high CPU utilisation can indicate limited headroom, but it should be evaluated alongside run-queue length, latency, throttling, workload concurrency and peak-demand measurements. A consistently busy CPU is not automatically undersized if service-level targets remain satisfied. When NVMe storage queues begin to back up because the drive count is fixed and the catalog does not offer additional slots, teams often respond by offloading data to a secondary server or a cloud object store.
That workaround introduces network latency into what was originally a local read operation, and the added complexity compounds over time. Similarly, when memory pressure forces the operating system to use swap space regularly, query response times degrade in ways that are difficult to attribute cleanly to any single cause — and therefore difficult to fix without addressing the underlying RAM constraint.
Capacity planning mismatches surface differently. A team that provisioned a server for a workload that has since grown — more concurrent users, a larger dataset, a new AI inference pipeline layered onto existing services — may find that upgrading within the same provider's catalog means jumping to a configuration that overshoots their needs in some dimensions while still falling short in others. That mismatch is the structural argument for a custom build.
When the catalog forces you to overbuy on storage to get the CPU you need, or accept slower RAM to stay within budget, the economics of a tailored configuration begin to make sense.
Recognizing these signals early is the prerequisite for a productive conversation with any provider. Shortlist providers with the provider comparison, then confirm custom-hardware handling directly before your workload forces the issue.
Negotiating Custom Configurations Before You Sign
Effective negotiation on custom dedicated server hardware starts before you contact a provider. The teams that secure the best outcomes arrive with a precise workload specification document rather than a general description of their needs. That document should state CPU core count and clock speed requirements, RAM capacity and speed grade, storage type and slot count, network port speed, and any specific peripheral requirements such as additional NIC cards or hardware security modules.
A provider receiving a structured spec sheet can assess feasibility and cost far faster than one asked to interpret vague performance goals.
The negotiation itself has two practical phases. In the first phase, you confirm whether the provider can source the components at all — and within what timeframe. Custom-build lead times and minimum commitments vary by component availability and provider policy. Obtain the expected delivery date, billing start date, minimum term and cancellation consequences in writing.
Accepting the agreed window in writing, with a clear start date for your billing cycle tied to actual delivery rather than order placement, is a basic contractual protection. In the second phase, you address the commercial trade-offs. A provider may require a longer minimum term or a non-refundable procurement commitment for a custom build. Confirm the exact term, ownership of purchased components and early-termination consequences in writing.
Knowing that in advance lets you evaluate whether the configuration's performance gains justify the reduced flexibility.
Written hardware commitments in the contract matter more than verbal confirmation during a sales call. The contract should name the specific component model, not just a category. "NVMe SSD storage" is not the same as a named drive generation with a specified read/write throughput rating. Providers offering genuine custom hardware flexibility will accommodate that level of specificity.
Those who resist committing to exact components in writing are signaling that substitution is possible after signing — a risk that has caught teams off guard well into their contract term.
A headline server price may not include procurement, installation, reserved-spares or enhanced-support charges. Request a complete cost breakdown before approving a custom build.
What Hidden Costs Emerge When You Customize Beyond the Catalog
Custom configurations can introduce costs that do not apply to standard catalogue servers. Possible charges include procurement, assembly, qualification, reserved spare parts, enhanced support and software licensing. Request an itemised quotation and confirm which charges are one-time, recurring or payable at renewal.
Custom configurations may add one-time assembly charges and, depending on the component, recurring support or licence costs — request an itemised quotation.
Custom configurations may introduce one-time assembly, qualification or procurement charges. Additional recurring costs can arise from vendor support, software licences, reserved spare parts or enhanced management services, but these charges depend on the component and provider. Request an itemised quotation covering installation, support, replacement and renewal costs.
A custom NIC configuration or an additional drive bay may add a modest flat charge. A fully bespoke memory layout or a hardware security module integration can carry a substantially higher one-time cost.
Replacement part lead times create a second, less visible cost. When a component in a custom build fails, the provider may not hold a spare on site. That gap extends hardware replacement windows beyond what a standard SLA promises — sometimes significantly. Some providers address this by requiring the buyer to fund a spare-parts reserve held in the data center, which adds a recurring inventory cost that never appeared in the original discussion.
Others simply extend the SLA language to accommodate the longer sourcing window, which shifts the operational risk entirely to the buyer.
Licensed RAID controllers, out-of-band management cards beyond the standard offering, and specialized firmware support can each add recurring monthly line items. These charges accumulate quietly alongside the base server fee.
Which Industries Push Custom Hardware Requests the Hardest?
Custom hardware requirements commonly arise in regulated environments, accelerator-intensive computing and high-throughput media processing. These are examples rather than an exhaustive or ranked list of industries requesting custom systems.
Each arrives at the custom hardware conversation through a different technical pressure, but all three share a common pattern — their workloads carry hard constraints that standard configuration tiers cannot absorb without modification.
Regulated industries, particularly those in financial services and healthcare, typically open the custom conversation around network isolation. Regulated organisations may request additional NICs, segmented network paths or hardware security devices to support their chosen security architecture. Whether these controls are required depends on the applicable framework, risk assessment and implementation scope; compliance should not be presented as automatically requiring dedicated physical traffic paths.
Depending on the applicable standard and assessment scope, buyers may need documentation covering the relevant system architecture, security controls, component class or specific device. Confirm the evidence required with the organisation responsible for the audit or assessment. Experienced buyers still push for written hardware commitments before procurement closes rather than accepting catalog descriptions at face value.
Large-model inference can be constrained by accelerator memory capacity, memory bandwidth, interconnect performance and host-to-device data transfer. Buyers should size the complete workload and request the required GPU model, accelerator memory, PCIe or interconnect topology, host RAM and power envelope rather than relying on a generic memory-to-processor ratio.
Media workloads may require different combinations of storage throughput, drive capacity, accelerator support and network bandwidth. Requirements vary significantly between encoding, streaming and content-processing pipelines.
Important pre-contract questions concern spare-part location, replacement commitments, provisioning delays and escalation outside normal support hours.
What Do Users Wish They Had Known Before Requesting Custom Hardware?
Important pre-contract questions concern spare-part location, replacement commitments, provisioning delays and escalation outside normal support hours. Failing to resolve those questions before ordering can create replacement, provisioning and support risks after deployment.
- Whether non-standard components are stocked on-site or must be sourced remotely before any replacement
- Exact contractual language defining acceptable provisioning delay windows for custom builds
- A named escalation path for component failures that occur outside standard support hours
- Replacement SLA terms specific to non-catalog parts, not just the general server SLA
- Which components in the custom build are most likely to be single points of supply chain failure
- Whether the provider has fulfilled this specific configuration before and at what volume
Standard components may be available from local stock, while non-catalogue parts may require external procurement. Confirm spare-part location and the replacement commitment for each custom component in writing before the server is provisioned.
Provisioning delays catch teams equally off guard. Custom-build lead times and minimum commitments vary by component availability and provider policy. Obtain the expected delivery date, billing start date, minimum term and cancellation consequences in writing.
Standard agreements may not explicitly address non-standard components. Review warranty coverage, replacement commitments, SLA exclusions and liability terms for every custom component.
Conclusion – Know Your Limits Before You Customize
Custom hardware requests reveal a provider's operational depth far more reliably than any catalog page does. The teams that navigate these negotiations successfully share one habit: they treat every non-standard component as a contract question before it becomes a support ticket. Replacement timelines, provisioning windows, SLA language, and escalation paths for out-of-hours failures must be resolved in writing before the server is built — not discovered under pressure after something fails.
Settle replacement timelines, SLA language, and escalation paths in writing before the server is built, not after it fails.
That preparation is not excessive caution; it is the minimum due diligence that separates a smooth deployment from a costly stall.
The practical next step is matching your specific workload requirements against providers that have a documented, repeatable process for custom builds.
Use the provider comparison to build an initial shortlist based on provider-level pricing, management, support, traffic, storage and commercial terms. Then send each shortlisted provider the same written hardware specification and request confirmation of component models, provisioning time, replacement coverage and contract terms.




