
A kernel panic is one of the most disorienting events a server operator can face. The machine stops without warning, logs cut off mid-sentence, and the only evidence left behind is a crash dump that most teams have never been trained to read. Without a structured approach, the investigation stalls: hardware gets swapped, kernels get rolled back, and the reboots keep happening anyway. Reading a crash dump is not reserved for kernel developers.
The core skill is knowing which fields matter, what they point to, and how to separate a hardware fault signature from a driver conflict or a kernel bug. Those three root causes look superficially similar in a panic message but require entirely different remediation paths. Treating a driver conflict as a memory fault wastes time and risks introducing new instability; treating a kernel bug as a hardware problem can send you chasing phantom errors across perfectly healthy components.
This article walks through the diagnostic logic behind crash dump analysis on a dedicated server: how to locate and open the dump, which fields carry the most diagnostic weight, and how to reason from a stack trace toward a confirmed root cause.
What a Kernel Panic Actually Tells You
A kernel panic is the operating system's last-resort safety mechanism: it halts all execution the moment it detects a condition from which it cannot safely recover. Unlike a clean reboot triggered by an administrator or a watchdog timeout that restarts a hung process, a The kernel itself reached a point where continuing would risk corrupting data, misaddressing memory, or executing invalid instructions. That distinction matters diagnostically. A clean reboot leaves almost no trace.
A panic — if your system is configured to capture it — preserves a detailed snapshot of exactly what the processor was doing at the moment of failure. That snapshot is called a crash dump, and reading it correctly is the difference between resolving the underlying fault and replacing hardware at random until the reboots stop.
The crash dump contains several layers of information, each narrowing the search space further. The outermost layer is the panic string: a short message such as "BUG: unable to handle kernel NULL pointer dereference" or "Oops: general protection fault." These strings are not arbitrary — each maps to a specific class of failure. A null pointer dereference typically points toward a driver or kernel module that attempted to access memory it was never allocated.
A general protection fault often signals an attempt to execute a privileged instruction from an unprivileged context, which can indicate a conflict or a corrupted code path. A machine check exception, by contrast, originates from the CPU's own hardware error-reporting registers and is the clearest early signal of a physical component problem.
Below the panic string sits the call trace: the ordered list of kernel functions that were active when the system halted. This is where the real diagnostic weight lives. Each function name in that trace narrows the investigation. A trace dominated by storage driver symbols points in a different direction than one filled with memory management or network subsystem calls.
Knowing how to read that sequence — rather than treating it as noise — is what separates a productive investigation from repeated component swaps that solve nothing. The sections that follow build exactly that reading process, from the first panic string through to a confirmed root cause.
Configuring your system to capture crash dumps before a panic occurs is a step that cannot be skipped, because once the server reboots without that setup in place, the evidence is gone permanently.
How Crash Dumps Are Generated and Where to Find Them
A crash dump only exists if your system was configured to write one before the panic occurred. Many engineers discover this gap at the worst possible moment: the server has rebooted, the panic is gone, and nothing was captured. Verifying your dump configuration is therefore the first step — not something to check after the fact. On Linux, the standard mechanism is a combination of kexec and kdump.
When the primary kernel panics, kexec boots a small, pre-loaded secondary kernel directly from memory. That secondary kernel has one job: write the contents of RAM to a designated dump file on disk, then hand control back. The dump file is typically written to a path such as /var/crash, though the exact location depends on your kdump configuration.
Confirming that kdump is active, that the reserved memory region is large enough for your installed RAM, and that the target partition has sufficient free space are the three checks to make before any panic occurs. A system with 64 GB or more of RAM needs a correspondingly sized reserved region — undersizing it produces a truncated dump that may be missing the exact memory pages you need most.
On Windows Server, the equivalent facility is the Memory Dump setting in the panel, which offers options ranging from a small minidump to a complete memory dump. Complete dumps are the most useful for root-cause work but also the largest; ensure the pagefile on the system volume is sized to accommodate the full RAM contents. When the OS cannot write to disk at all — a common scenario with hardware-level panics — out-of-band capture becomes essential.
The baseboard management controller (BMC) logs hardware events independently of the operating system, and Serial-over-LAN access via the IPMI interface lets you read the console output that appeared just before the system halted. These two sources often contain the panic string and partial call trace even when no dump file was written. A well-configured dedicated server environment treats out-of-band access as a mandatory diagnostic layer, not an optional add-on.
The BMC event log and serial console together frequently provide enough context to identify whether the panic originated in hardware or software — narrowing the investigation before the dump is even opened.
Reading the Panic String: Decoding the First Three Lines
The first three lines of a panic string contain enough information to identify the fault class in most cases. Reading them in order — fault type, faulting address, then the call trace header — gives you a structured starting point rather than a wall of undifferentiated text.
A corrupted stack can redirect your entire investigation toward the wrong subsystem before you read past line one.
Where this process breaks down is when the faulting address itself is misleading: a corrupted stack can cause the CPU to report an address that belongs to a completely unrelated subsystem, sending the investigation in the wrong direction from the first line.
The harder judgment call arises when the same fault type appears repeatedly across different modules after a kernel or hardware change — that pattern shifts suspicion away from any single driver and toward a shared dependency, a mismatched kernel ABI, or a memory subsystem fault that is corrupting pointers before they are ever dereferenced.
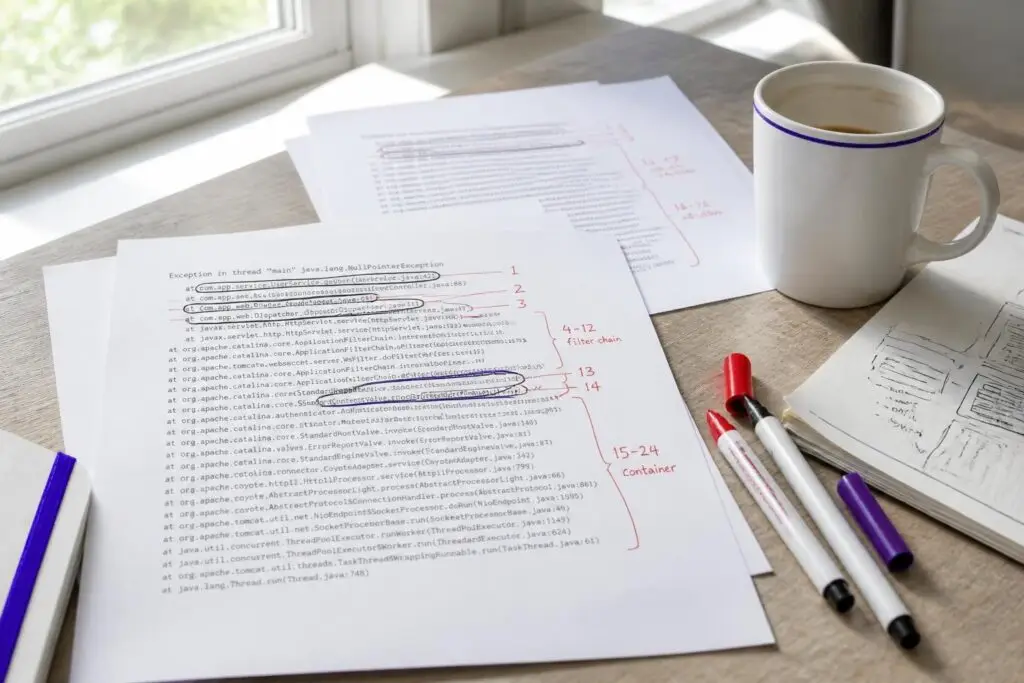
Scheduler and interrupt-handling frames can obscure the true origin of a fault deep within the call trace, making it essential to work methodically through each frame rather than blaming the first suspicious module you encounter.
Analyzing the Call Trace to Pinpoint the Faulting Module
, scheduler and interrupt-handling frames can dominate the upper stack, burying the faulting module several frames deeper than expected and making an innocent subsystem appear responsible.
The threshold question is whether the trace is even trustworthy. A panic caused by stack corruption may have overwritten the very return addresses the trace relies on, producing a sequence of functions that never actually called one another.
Before investing time in a frame-by-frame analysis, confirm that the stack pointer reported in the panic header falls within a plausible kernel stack range; a wildly out-of-range value is a strong signal that the trace itself is an artifact of the corruption rather than a record of it.
How Do You Tell Whether the Panic Came from Hardware or Software?
Hardware faults and software bugs can produce nearly identical panic signatures, which means misattributing one for the other sends your diagnosis in the wrong direction from the first step. The clearest early separator is the Exception log. When a processor detects an uncorrectable hardware error — a failing memory cell, a PCIe bus fault, or a cache coherency failure — it records a structured entry in the MCE log before the panic fires.
That entry contains a bank number, a status register value, and an error type code. A panic preceded by MCE entries points firmly toward hardware. A panic with no MCE history points toward a driver regression, a kernel bug, or a corrupted module. The second diagnostic layer is corrected error counts.
The kernel's EDAC subsystem tracks memory errors that were corrected before they caused data corruption. Checking the counters under the edac device path in the system filesystem reveals whether your DIMMs have been silently accumulating corrected errors over hours or days. A rising corrected error count on a specific memory rank, even without a panic, is a hardware warning that precedes an uncorrectable fault.
Zero corrected errors across all ranks, combined with a panic tied to a specific driver frame in the call trace, shifts the probability decisively toward software. The recurrence pattern under load versus idle provides a third signal. Hardware faults — particularly thermal stress on a DIMM or a marginal PCIe connection — tend to surface under sustained memory bandwidth or I/O pressure, then disappear during idle periods.
Software bugs, by contrast, often trigger at a specific code path regardless of load level: the same module appears at the top of the call trace every time, even on a lightly loaded machine. Tracking both the system load at the time of each panic and the EDAC counters across multiple events builds a pattern that distinguishes the two root causes with confidence.
- Check the MCE log for structured entries containing bank number, status register value, and error type code before the panic timestamp
- Query the EDAC subsystem for corrected memory error counts that spiked before the fatal event
- Look for PCIe bus fault codes or cache coherency failure entries in the exception log
- Confirm whether the panic string references a specific hardware address or a kernel NULL pointer, which favors software
- Cross-reference the panic timing with any recent hardware changes such as new DIMMs, PCIe cards, or firmware updates
- A panic with zero MCE history and a bracketed module name in the call trace points toward a driver or kernel bug rather than failing silicon
Third-party kernel modules become especially dangerous after a kernel version update, because even a minor ABI change can silently break a module's assumptions and trigger a panic that appears unrelated to the update itself.
Driver Conflicts and Kernel Module Failures as Panic Triggers
Third-party kernel modules are among the most frequent on dedicated hardware, and the risk rises sharply immediately after a kernel version update. When the kernel's internal ABI changes — even a minor version bump can alter function signatures or data structure layouts — an out-of-tree module compiled against the previous version may dereference a null pointer or write to an invalid memory address the moment it initializes.
Blacklisting a suspect module costs one reboot and delivers a reproducible answer instead of an educated guess.
The result is a panic that appears hardware-related but traces entirely to a driver mismatch. The call trace is the primary instrument here. When a module is the culprit, its name typically appears in the first few frames of the trace, either as the faulting instruction's owner or as the function that passed a bad pointer to a core kernel routine.
Once you have identified the suspect module name, the most controlled next step is module blacklisting: add the module to the kernel's blacklist configuration, reboot, and observe whether the panic recurs. If the system remains stable without the module loaded, the driver is confirmed as the trigger. This approach avoids the need for a datacenter visit and produces a reproducible result rather than a guess.
Storage controller drivers, out-of-tree network interface drivers, and GPU compute drivers are the three categories most commonly implicated on bare-metal hardware running production workloads. After confirming the module, version correlation becomes the remediation path. Check the driver's release notes against the kernel version currently running.
Many vendors publish updated out-of-tree modules that restore ABI compatibility after a kernel update; loading the corrected version and running a deliberate stress cycle — sustained I/O or compute load for several hours — validates the fix before returning the server to production.
For teams who want a structured workflow covering blacklisting, version pinning, and stress validation in one place, our dedicated server recommendation outlines the operational depth to look for when selecting a provider.
Why Does the Server Keep Rebooting Even After a Kernel Update?
Persistent reboots after a kernel update do not always mean the new kernel is faulty. In many cases, the update itself succeeded, but a secondary failure — in the initial RAM filesystem, the bootloader configuration, or the hardware watchdog layer — creates a reboot loop that looks identical to a recurring panic. The first place to check is the initramfs image. When a new kernel installs, the system must rebuild this image to include the drivers and modules needed for early boot.
If that rebuild step fails silently — due to a disk space shortage, a hook script error, or an interrupted package transaction — the machine boots the new kernel but cannot mount the root filesystem. The result is an immediate failure that the bootloader records as an unsuccessful boot attempt. Many bootloaders are configured to fall back to the previous kernel entry after a set number of failed boots, which creates the illusion of stability until the next maintenance window triggers the same cycle again.
Inspecting the bootloader's recorded boot attempt counter and comparing it against your expected value exposes this loop quickly. The second, less obvious cause sits below the OS entirely. Hardware watchdog timers — built into server management controllers — are designed to reset the machine if the OS stops responding within a defined timeout window. After a kernel update, a driver change can prevent the watchdog daemon from sending its regular keepalive signal.
The watchdog then resets the server, and the event appears in the BMC system event log rather than in a kernel crash dump. Checking the out-of-band event log alongside the OS-level logs is the only way to distinguish a watchdog-triggered reset from a genuine kernel panic. Confirming stability before returning to production requires more than a single clean boot.
Running the server under realistic load for a sustained period — while monitoring both the OS uptime counter and the BMC’s event log simultaneously — gives you two independent confirmation signals.
Matching the crash dump against the journal log, the kernel ring buffer, and the hardware event log together reveals a chronological sequence of failures that no single source could expose on its own.
Correlating Crash Dumps with System Logs and Hardware Event Records
A single crash dump rarely tells the complete story. The events recorded in the journal daemon’s persistent log, the kernel ring buffer snapshots written before shutdown, and the hardware’s system event log together form the timeline that either confirms or eliminates each hypothesis you formed from the dump alone. Without that timeline, you are diagnosing the moment of failure while ignoring the minutes or hours that caused it.
, provider selection matters for structured remediation workflows. The more pressing constraint here is that correlation only holds when log retention is long enough to cover the pre-failure window—if your journal is capped at a size that rolls over within hours under heavy I/O, corrected hardware error entries from the critical period before the panic may already be gone before any engineer opens a terminal.
Once aligned, look for corrected hardware error entries in the log. These are recoverable memory or PCIe errors that the hardware silently fixed without crashing the system. A burst of such entries in the two to four hours before a panic is a strong indicator that a hardware component was degrading under load before the OS reached its tolerance limit. The second layer to examine is the kernel ring buffer output captured immediately before the crash.
This buffer often contains I/O error sequences, memory controller warnings, or firmware timeout messages that do not appear in the crash dump itself. Comparing that output against the BMC’s event log at matching timestamps reveals whether the kernel's final state was a consequence of an infrastructure-level fault — such as a storage controller reset or a power delivery anomaly — rather than a software defect.
When the evidence consistently points to infrastructure, escalate to the provider with the crash timestamp, kernel dump, kernel log, and any available BMC or hardware event log—not merely a general kernel log file.
- Convert all log timestamps to a single reference frame before drawing any conclusions — OS journal, kernel ring buffer, and hardware event log each use different clock sources
- Check the kernel ring buffer snapshots written before shutdown for error messages that preceded the panic by minutes or hours
- Review the hardware system event log for thermal events, power fluctuations, or corrected errors that align with the crash window
- Identify whether any scheduled job, cron task, or deployment pipeline fired within the correlation window immediately before the panic
- Look for repeated corrected errors in hardware logs that escalated to an uncorrectable fault at the moment of the crash
- Confirm that the crash dump timestamp matches the last journal entry to rule out clock drift misattribution
- Use the seconds-since-boot value from the kernel ring buffer to anchor the sequence of events relative to the panic frame
Kernel Panic Root Cause Types: Diagnostic Comparison
| Criterion | as | var | crash |
|---|---|---|---|
| Panic string signature | NULL pointer dereference or general protection fault | MCE or hardware error-reporting register fault | Oops with corrupted code path or invalid instruction |
| Call trace dominant symbols | Driver or kernel module function names dominate trace | Memory management or CPU exception handler symbols | Mixed subsystem symbols; no single dominant driver |
| Remediation path | Identify conflicting module; update or remove driver | Inspect physical components; check RAM and CPU | Roll back kernel version or patch specific code path |
| Risk of misdiagnosis | Often mistaken for hardware fault; wastes component swaps | Clearest hardware signal; least ambiguous root cause | Easily confused with driver conflict; prolongs investigation |
Conclusion – From Raw Crash Dump to a Confirmed Fix
Reading a kernel crash dump is not a single action — it is a structured sequence that moves from the panic string and faulting module through memory state, call stack, and hardware event records to a confirmed root cause. Each layer either narrows the hypothesis or eliminates it. A driver conflict leaves a different signature than a memory fault, and a watchdog-triggered reset leaves a different trail than a genuine kernel panic.
A driver conflict, a memory fault, and a watchdog reset each leave distinct signatures that demand different fixes.
Treating these failure signatures as interchangeable is a common reason unexplained reboots persist. If the dump points to interrupt handling rather than a driver or memory fault, continue with Dedicated Server High Interrupt Load — IRQ and SoftIRQ Diagnosis.




