
A dedicated server running at full capacity should distribute interrupt processing evenly across available CPU cores. When it does not, a single core saturates while the rest sit underutilized — and the symptom surfaces as unexplained latency spikes, degraded network throughput, or a ksoftirqd process consuming CPU time that belongs to your application. The root cause is rarely obvious from a top-level CPU utilization chart alone.
High interrupt load on a dedicated server typically falls into one of three categories: hardware IRQ contention, where a network card or storage controller floods a single CPU core with interrupt requests; softIRQ saturation, where the kernel's own deferred processing queue becomes a bottleneck; or a misconfigured CPU affinity policy that routes all interrupts through core zero by default.
Each category has a distinct diagnostic fingerprint, and treating the wrong one wastes time while the real cause persists. Understanding which category applies to your situation is the first step before any configuration change is made. This article walks through the diagnostic logic behind IRQ and softIRQ analysis on dedicated hardware — from reading the right counters, to identifying whether receive-side scaling or interrupt affinity tuning is the appropriate lever.
What Is High Interrupt Load on a Dedicated Server?
High interrupt load occurs when the volume of hardware or software interrupt requests exceeds what a single CPU core can process in time, causing that core to saturate while adjacent cores remain largely idle. On a dedicated server, this imbalance is not a sign of overall CPU exhaustion — it is a scheduling problem, and the distinction matters enormously for how you approach diagnosis. Reaching for additional compute capacity before confirming the root cause will not resolve the condition.
A hardware interrupt, or IRQ, is a signal sent by a physical device — most commonly a network card or storage controller — to alert the CPU that it requires attention. The kernel pauses its current execution context, runs a short interrupt service routine to acknowledge the device, and returns. Under light traffic, this cycle is imperceptible.
Under sustained high-throughput workloads, a NIC receiving tens of thousands of packets per second can fire interrupts so rapidly that the assigned core spends more time servicing the device than executing application threads. The clearest field indicator is a single core pinned near 100% in the hi field of a CPU utilization breakdown, while every adjacent core shows normal figures. That pattern points directly to interrupt routing as the bottleneck, not raw compute capacity.
Software interrupts — softIRQs — represent the kernel's deferred processing layer. When a hardware interrupt fires, the kernel completes only the minimum necessary work immediately, then schedules a softIRQ to handle the remainder asynchronously. The ksoftirqd kernel thread carries out this deferred work on a per-core basis.
When softIRQ demand outpaces processing capacity, ksoftirqd begins consuming significant CPU time and appears in monitoring output as a process competing directly with your application workload. This is a distinct condition from hardware IRQ saturation, even though both frequently originate from the same high-traffic NIC.
Mapping IRQ counts per core, identifying softIRQ categories by type, and correlating both against network throughput metrics is the diagnostic foundation from which every effective remediation step follows.
A sudden divergence in per-core CPU utilization, visible through repeated sampling of /proc/interrupts, is often the first measurable sign that hardware interrupt processing is overwhelming specific cores.
How Do You Spot IRQ and SoftIRQ Saturation Early?
The earliest reliable signal of interrupt saturation is a divergence between per-core CPU utilization figures — climbing toward 100% in the hardware interrupt field while the rest remain relaxed.
A single NIC queue mapped to one CPU can appear as a rapidly increasing interrupt count in that CPU column while the other columns remain comparatively quiet.
The %irq field shows hardware-interrupt CPU time, while %soft shows softIRQ time. A ksoftirqd/N thread consuming substantial CPU identifies the affected logical CPU, which can then be correlated with the corresponding column in /proc/interrupts.
Capturing softIRQ and hardware interrupt rates over a rolling window — rather than a single snapshot — separates a transient burst from a structural saturation pattern.
Tracing the Interrupt Source: NIC Drivers, Storage Controllers, and Beyond
Once elevated interrupt counts are visible in the per-core data, the next step is mapping those counts to a specific device. The left column of /proc/interrupts lists each IRQ line by number, and the rightmost column names the device or driver responsible. Sorting that output by the highest delta count across a two-second capture interval immediately identifies which IRQ line is generating the most events — and therefore which physical device is the origin of the load.
A NIC with all queues pinned to one CPU can saturate that CPU while neighboring cores handle almost no interrupt work.
High-throughput network interface cards are the most frequent source on bare-metal hardware under sustained traffic. A multi-queue NIC assigns each hardware queue its own IRQ line, so the interrupt listing will show several consecutive IRQ numbers sharing the same driver name. If all of those queues are mapped to a single core — a common default after a driver installation — the interrupt count on that core accumulates rapidly while the queues on other cores show near-zero activity.
Running lspci with verbose output identifies the NIC's hardware generation and driver binding, which matters because older driver versions often default to single-queue mode regardless of the card's physical queue capacity.
NVMe storage controllers are the second most common source of interrupt-driven CPU saturation on modern dedicated hardware. Each NVMe namespace can expose multiple completion queues, each generating its own interrupt stream. A controller with several active queues, all mapped to the same core, produces an interrupt pattern that closely resembles NIC saturation in the raw counts — making the lspci device class field essential for distinguishing the two.
Storage-driven interrupt storms tend to correlate with sustained sequential write workloads rather than network throughput spikes. Correlating the interrupt-rate increase with storage throughput and latency is the useful separator during diagnosis.
Other devices — PCIe expansion cards, RAID controllers with large write-back caches, and USB host controllers in some configurations — can also appear in elevated IRQ counts, though far less frequently on purpose-built server hardware. Checking the interrupt type column within /proc/interrupts distinguishes MSI-X interrupts, which support per-queue affinity, from legacy level-triggered interrupts, which do not.
Only MSI-X capable devices respond to affinity tuning; knowing this before attempting remediation prevents wasted effort.
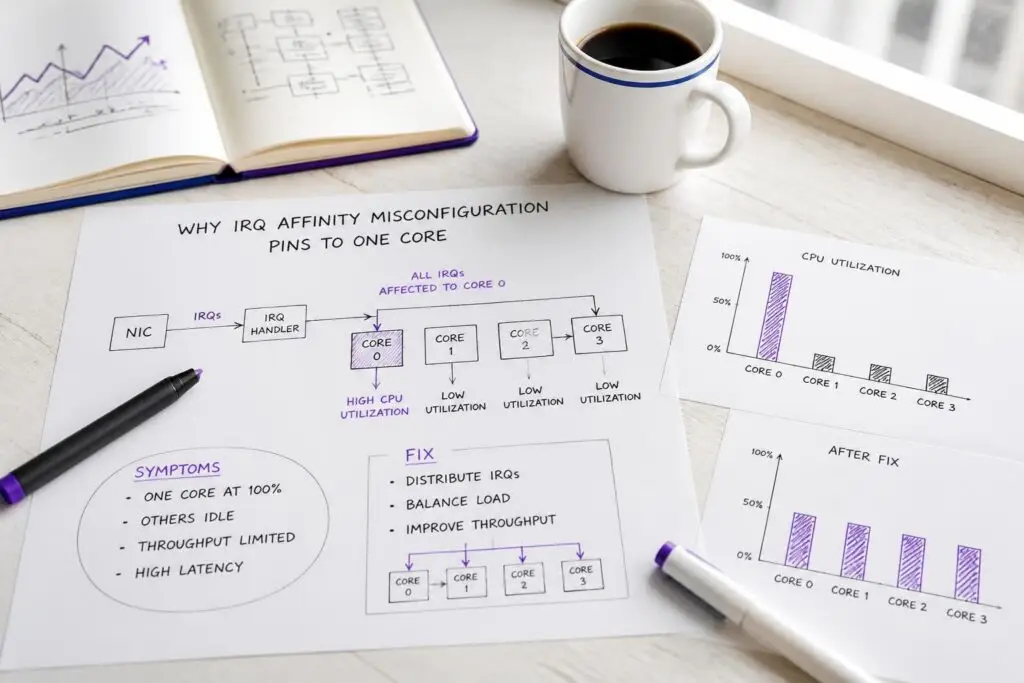
Default interrupt balancing routines frequently leave high-rate network interface lines pinned to a single core, creating a hidden bottleneck that manual affinity tuning must deliberately correct.
Why IRQ Affinity Misconfiguration Pins Load to One Core
What that workflow must account for, however, is a subtlety the default tooling obscures: the kernel's built-in IRQ balancer does not treat all interrupt lines equally. High-rate lines — particularly those servicing multi-queue NICs under sustained traffic — are frequently pinned to their initial core and never migrated, even when the balancer is active, because the balancer's cost heuristics deprioritize lines it classifies as already "owned" by a driver.
The value of 0-31 in /proc/irq/N/smp_affinity_list is not a guarantee of distribution; it is a permission boundary the balancer may never exercise. The practical decision rule is to treat any high-count IRQ line whose delta in /proc/interrupts accumulates exclusively on one CPU column as misconfigured, regardless of what the affinity mask nominally permits, and to apply an explicit echo to smp_affinity_list rather than relying on automatic rebalancing.
The kernel exposes each interrupt line's current affinity assignment through the file at /proc/irq/N/smp_affinity_list, where N is the IRQ number identified in the earlier device-mapping step. That file contains a human-readable list of the CPU cores permitted to handle the interrupt. A value of 0 means only core 0 is eligible.
A value of 0-31 means the kernel may balance across all cores in that range — but may not, because the kernel's built-in IRQ balancer is conservative and often leaves high-rate interrupt lines on their initial core unless explicitly instructed otherwise. Reading this file for each high-count IRQ line takes under a minute and immediately confirms whether affinity misconfiguration is the root cause or whether a different problem — such as driver-level queue limits — is responsible.
One important nuance: the irqbalance daemon, when running, rewrites these affinity files periodically based on load heuristics. If irqbalance is active and misconfigured, manual affinity changes are overwritten within seconds, making the saturation pattern reappear. Checking whether irqbalance is running — and what policy it applies — is therefore a required step before any affinity change takes effect durably.
Redistributing Interrupt Load: IRQ Affinity, RSS, and RPS Tuning
Three complementary mechanisms address interrupt load imbalance: manual IRQ affinity pinning, Receive Side Scaling (RSS) at the hardware level, and Receive Packet Steering (RPS) as a software fallback.
Choosing the right mechanism depends on what your NIC hardware supports — applying the wrong one wastes time and leaves the saturation pattern unchanged. One practical constraint before touching any affinity file: confirm whether irqbalance is running, because it will periodically overwrite your assignments based on its own load heuristics.
- Confirm MSI-X support on the NIC before attempting any affinity pinning — without it, manual pinning has no effect.
- Write CPU bitmasks to each high-count IRQ line's
smp_affinityfile to spread hardware interrupt work across distinct physical cores - Pin each queue of a multi-queue NIC to a separate core so no single core absorbs all hardware interrupt events
- Use Receive Side Scaling (RSS) when the NIC hardware supports multiple queues — it distributes interrupt handling without manual per-IRQ configuration. Fall back to Receive Packet Steering (RPS) only when the NIC is single-queue and RSS is unavailable, as it operates in software and adds overhead.
- Check whether an IRQ balancing daemon is running — it will periodically overwrite manual affinity assignments and restore the original imbalance
Manual affinity pinning is the correct starting point when the earlier diagnostic steps have confirmed that a small number of IRQ lines are bound to core 0 and the device supports MSI-X.
Writing a CPU bitmask to the smp_affinity file for each high-count interrupt line distributes those lines across a set of cores.
A four-queue NIC, for example, can have each queue's interrupt pinned to a distinct physical core, spreading the hardware interrupt work evenly. If irqbalance is running, either disable it or configure its policy file to exclude the specific IRQ lines you have pinned manually; mixing both approaches produces unpredictable results. RSS applies when the NIC firmware itself supports multi-queue hashing.
In that case, the hardware distributes incoming flows across multiple receive queues before the kernel ever sees the packet, and each queue raises interrupts on a separately pinned core.
When ksoftirqd threads consume significant CPU time despite evenly distributed hardware interrupt counts, the underlying problem is a growing backlog of deferred kernel work rather than any affinity misconfiguration.
What Causes ksoftirqd Spikes Even When Hardware IRQs Look Normal?
Elevated ksoftirqd CPU consumption with balanced hardware interrupt counts points to a software interrupt backlog, not a hardware affinity problem. The kernel defers certain work from the hard interrupt handler into a softirq context, and when that deferred work accumulates faster than it is processed, the ksoftirqd threads step in to drain the queue. Three distinct sub-causes produce this pattern, and they require different diagnostic commands to separate.
Ksoftirqd steps in only when deferred kernel work piles up faster than the system can drain it.
The most common cause is NET_RX softirq backlog exhaustion. Under high packet rates, the kernel's NAPI polling mechanism processes a bounded number of packets per interrupt cycle — the poll budget. When incoming traffic exceeds that budget before the cycle ends, the remaining packets stay queued and ksoftirqd is scheduled to continue processing. Reading the per-CPU softirq counters in the proc filesystem reveals whether NET_RX dominates the softirq count.
If it does, and if the NIC's NAPI budget is at its default, raising the budget per queue is the correct lever. Confirming whether the driver respects a configurable weight parameter is a prerequisite; not all drivers expose that setting.
A second, less obvious cause is timer-driven softirq accumulation. High-resolution timers and network timeout callbacks fire as TIMER or HRTIMER softirqs. When a large number of TCP connections each carry short keepalive intervals, the aggregate timer load can saturate a single core’s softirq processing without any corresponding spike in hardware interrupt counters. Measuring the TIMER softirq rate separately from NET_RX in the same proc output distinguishes this scenario cleanly.
A third cause is RX ring buffer overflow: packets are dropped before NAPI even polls them, which reduces visible softirq counts but introduces retransmissions that generate secondary softirq load. Checking the NIC’s dropped and missed counters surfaces this condition. A structured diagnostic guide — covering NAPI budget tuning, timer softirq isolation, and ring buffer sizing as a sequential workflow — provides the exact remediation path for each sub-cause.
Validating the Fix: Metrics to Confirm Interrupt Balance Is Restored
Interrupt rebalancing is confirmed — not assumed — by re-reading the same per-CPU counters you used during diagnosis and verifying that the distribution has shifted measurably. Closing an incident without this step risks reopening it hours later when traffic patterns shift and the original imbalance reasserts itself.
Start with the affinity assignments themselves. Reading each interrupt line's smp_affinity_list file confirms which CPU mask is currently active. A mismatch between what you configured and what the file reports indicates that a running service — most commonly an automatic IRQ balancing daemon — has overwritten your assignment. If that daemon is still active, its periodic rebalancing will undo manual affinity pinning on every cycle.
Disabling it for the affected interrupt lines, or stopping it entirely when RSS handles distribution at the hardware level, is a prerequisite before any measurement is meaningful.
Once the assignments are stable, compare per-CPU interrupt deltas across a sustained traffic window using a tool that samples at short intervals. The goal is a distribution where no single core carries a disproportionate share of the total interrupt count. A practical threshold: if the busiest core handles more than twice the interrupt volume of the least-loaded eligible core over a five-minute window, the distribution is still uneven enough to warrant further adjustment.
Monitor ksoftirqd CPU share on each core during the same window. A well-tuned system shows ksoftirqd consuming a small, roughly equal fraction of CPU time across the pinned cores — not a residual spike on the previously saturated core.
A structured diagnostic resource that sequences these verification steps as a post-remediation checklist, and flags when to escalate versus tune further, provides the operational closure that this overview is designed to point toward.
Continuously accelerating interrupt counters that fail to respond to affinity adjustments are a strong indicator of an underlying hardware fault demanding physical inspection rather than further software tuning.
When High Interrupt Load Points to a Deeper Hardware Fault
Compare interrupt growth with actual network throughput. A counter that continues rising rapidly while traffic remains minimal may indicate a flapping link, failing NIC, driver reset loop, or PCIe problem rather than an affinity issue. Check the kernel log for repeated link-state changes, PCIe errors, and driver-reset messages before changing affinity again.
Interrupt Load Diagnosis Approaches: Affinity, RSS, and RPS Compared
| Criterion | Affinity | RSS | RPS |
|---|---|---|---|
| Scope of fix | Routes specific IRQs away from core zero manually | Distributes NIC queue interrupts across multiple cores | Spreads packet processing across cores in software |
| Kernel layer addressed | Hardware IRQ routing at the interrupt controller level | Hardware IRQ and queue assignment inside the NIC | SoftIRQ processing layer only, no hardware IRQ change |
| Requires hardware support | No; managed via smp_affinity mask in procfs | Yes; NIC must support multiple hardware receive queues | No; purely kernel-side, works on single-queue NICs |
| Typical diagnostic trigger | One core pinned high in %irq while others idle | Multiple IRQ lines all mapping to the same core | ksoftirqd consuming CPU while %irq appears balanced |
| Configuration mechanism | Write CPU bitmask to /proc/irq/N/smp_affinity | Set queue count via ethtool combined or rx channels | Write CPU bitmask to /sys/class/net/ethX/queues/rx-N/rps_cpus |
Conclusion – Resolve IRQ Contention Before It Becomes an Outage
High interrupt load on a dedicated server is not a single problem — it is a layered one. The diagnostic path moves from symptom to kernel counter, from counter to affinity configuration, from affinity to RSS and RPS tuning, and finally to hardware fault indicators when software remediation reaches its limit.
Identifying the active layer before touching any setting cuts resolution time faster than any single tuning change.
Each layer has a distinct signature: a static imbalance concentrated on one CPU points to affinity misconfiguration; an accelerating aggregate interrupt count that ignores tuning may indicate a failing device; and ksoftirqd saturation without a matching hardware-IRQ spike points to a softIRQ backlog. Recognizing which layer is active before making changes is what separates a fast resolution from a cycle of adjustments that leaves the root cause untouched.
The framework in this article gives you the diagnostic sequence to work through each layer systematically — from reading interrupt counters and kernel ring buffer messages to verifying affinity assignments and confirming hardware fault indicators. Applying that sequence consistently means fewer guesses, shorter resolution windows, and a clear escalation point when the problem moves beyond kernel tuning.




