
Striking the right balance between under-collection and over-collection is essential, because audit gaps are far harder to justify after an incident than the upfront cost of a well-scoped ingestion boundary.
How to Define Log Sources and Scope Before Building the Pipeline
Once the stack exists, the boundary question becomes the critical next step.
The practical risk here is asymmetric: under-collection creates audit gaps that are difficult to explain after the fact, while over-collection inflates storage costs and drowns correlation rules in irrelevant events. Each framework draws that boundary differently, so the safest starting point is a written inventory that lists every logical component, its log format, and its expected event volume before a single pipeline rule is written.
Start with a written boundary document. The practical question is which logical components within that hardware require log coverage.
At minimum, the following layers typically fall within scope for all three frameworks: the operating system's authentication and privilege subsystem, the network interface and firewall rule engine, any database engine storing regulated data, the web or application tier handling user sessions, and scheduled task or cron activity that could modify system state. Each layer must be listed explicitly, with its log format and expected event volume noted, before normalization decisions are made.
Without this inventory, correlation rules are built on an assumed perimeter that may not match the auditor's view.
Over-collection is a real risk. Pulling in verbose application debug logs or low-level kernel I/O events inflates storage costs, degrades correlation performance, and forces analysts to filter noise manually. The correct approach is to define minimum necessary coverage for each framework, then add sources only when a specific control requirement demands it.
The implementation system covered in this guide builds directly on that inventory to enforce scope discipline at the pipeline level.
How to Structure Log Collection and Forwarding on Bare Metal
, the foundation log stack is a prerequisite — but reliable collection on bare metal adds its own sequenced decisions: which agent runs on each source, how events travel to the central collector, and what happens when that transport path is interrupted. The last question is the one most implementations defer until it causes an evidentiary gap.
A local event queue is not optional — losing 90 seconds of authentication logs during a collector outage can void an entire audit period.
Agent selection begins with the log surface. Kernel-level events — authentication attempts, privilege escalation, and system call activity — are best captured through the operating system’s native audit subsystem rather than a generic syslog relay, because a relay introduced mid-chain adds a failure point with no local queue of its own. That queuing constraint, not agent feature sets, should drive the selection decision in regulated environments.
The critical constraint for regulated environments is that the agent must guarantee at-least-once delivery: if the collector is temporarily unreachable, events must queue locally and flush in order when the connection recovers. A dedicated server's single-tenant storage makes local buffering straightforward — there is no competing tenant consuming disk I/O or interfering with queue integrity.
Encrypting the forwarding channel with a current TLS configuration satisfies this control and provides the documented transport boundary an auditor will request.
Beyond encryption, the forwarding path itself should be isolated. Where supported, use a dedicated network interface, VLAN, or separate logical network for log traffic so application congestion cannot affect collection reliability. This separation can be implemented on bare-metal and virtualized infrastructure, although the available controls depend on the hosting platform.
The correlation and alerting pipeline built on top of this collection architecture is where compliance-specific value is produced — and that is precisely what the implementation system in this guide addresses.
Without a consistent normalization layer that maps vendor-specific log formats to a shared schema, even well-written correlation rules will fire unpredictably and produce results that auditors cannot rely on.
How to Normalize and Enrich Events for Consistent Correlation
Normalization is the step that transforms raw, vendor-specific log strings into a structured, comparable format — and without it, correlation rules fire inconsistently or not at all. Before any alert can be meaningful to an auditor, every event entering the pipeline must share a common field schema: the same field name for a source IP address regardless of whether the event originated from a web server, a database engine, or the kernel audit subsystem.
Field mapping to a common event schema is the first task. A failed authentication attempt logged by an SSH daemon and one logged by an application server will use different field names, different severity labels, and different timestamp formats in their raw output. A normalization layer — sitting between the collection agent and the correlation engine — reads each event type and maps it to a shared structure.
Source host, event category, user identity, outcome, and timestamp become consistent fields across every source. Without this mapping, a correlation rule designed to detect repeated authentication failures across multiple services will miss events simply because the field names do not match.
Timestamp normalization deserves particular attention in bare-metal environments where multiple services may log in local time, UTC, or with differing precision. Consistent UTC alignment across all sources is not a stylistic preference; it is the prerequisite for accurate time-window correlation and for producing an event timeline that an auditor can follow without ambiguity.
Contextual enrichment adds a second layer of value. Mapping each event's source IP or hostname to an asset inventory — server role, environment classification, and compliance scope — transforms a raw authentication event into a statement that an auditor can immediately interpret. A login from a host classified outside the cardholder data environment carries different risk weight than the same event from a scoped system.
This enrichment step is where the scope discipline established during log source definition pays off operationally.
For teams ready to move from normalized events into actionable detection, the implementation system covered in this guide shows exactly how to structure correlation rules and alert thresholds against this enriched data model.
How to Build Correlation Rules That Map Directly to Compliance Controls
Correlation rules produce compliance value only when each rule traces back to a specific control requirement — not to a generic security intuition. A rule that fires on "unusual login activity" is useful for threat detection but useless as audit evidence.
The distinction between threshold-based rules and behavioral baseline rules determines what category of evidence each alert produces. Threshold rules are deterministic: they evaluate a fixed condition against a fixed window and fire when the count is met.
Behavioral baseline rules serve a different audit purpose. They detect deviation from an established pattern — a host sending significantly more outbound traffic than its seven-day average, or a service account authenticating at an hour with no prior precedent.
Without that documented baseline, an auditor cannot evaluate whether the threshold was meaningful.
Rule-to-control traceability is the operational habit that separates a functional SIEM from an audit-ready one. Every rule in the correlation engine should carry a metadata field recording which framework control it satisfies, what evidence artifact it produces, and what action the alert requires.
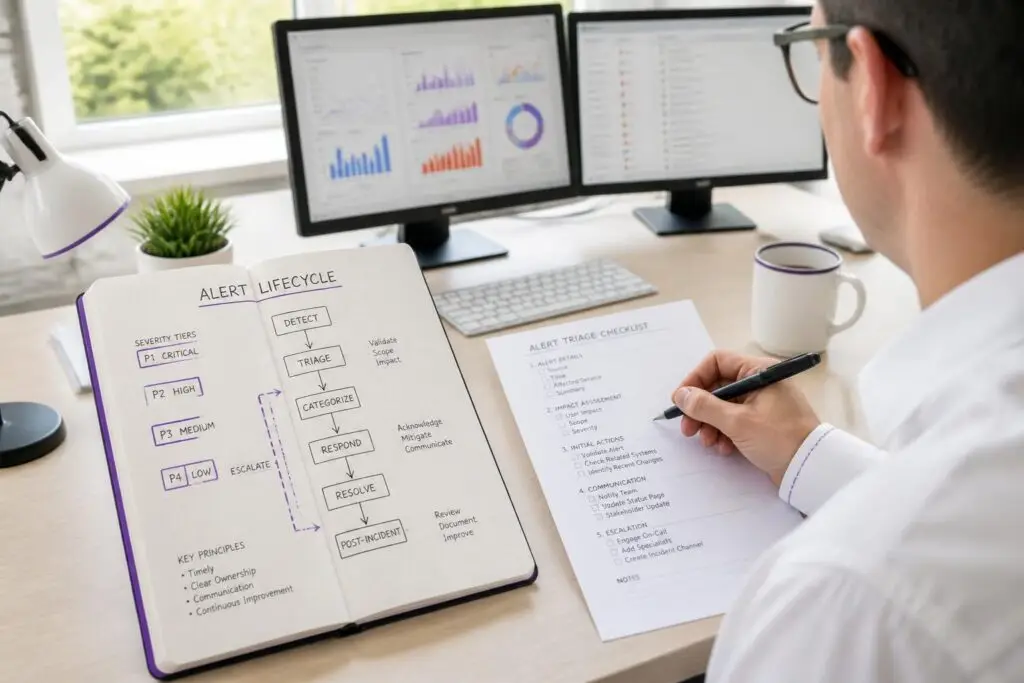
Every triggered alert must carry a complete, documented lifecycle — including severity classification, ownership assignment, and resolution record — before it qualifies as defensible compliance evidence rather than a timestamped notification.
How to Design Alerting Workflows That Produce Auditor-Ready Evidence
An alert that fires and disappears into a notification queue is not compliance evidence — it is noise with a timestamp. Alerting workflows produce auditor-ready artifacts only when every triggered alert carries a documented lifecycle: a severity classification, a routed destination, an acknowledgment timestamp, and a resolved or escalated state. Without that lifecycle, an auditor reviewing your SIEM output sees a list of events, not a list of responses.
Every alert needs four documented states — classified, routed, acknowledged, and resolved — before it qualifies as compliance evidence.
Severity classification is the first structural decision. Alerts should map to a tiered severity model — critical, high, medium, and informational — where each tier carries a defined response window.
A critical alert on a cardholder data environment host, for example, should require acknowledgment within a defined window, and that window must match what your incident response policy states. If the two diverge, an auditor will identify the gap.
Routing rules determine where each alert lands and who is accountable for its resolution. Alerts routed to a ticketing system create a record that includes the original event, the assignee, the acknowledgment time, and the closure note. That ticket reference becomes the compliance artifact that links the SIEM alert to a documented human response.
The implementation system described in this guide structures alert routing, severity mapping, and ticket integration as a single configured workflow, so each triggered rule produces a complete evidence chain without manual assembly after the fact.
How to Validate and Tune the Pipeline Without Breaking Compliance Coverage
Validating a SIEM log pipeline means confirming that every rule fires correctly under controlled conditions before a real incident tests it for you. The safest method is synthetic event injection: you generate log entries that deliberately match each correlation rule's trigger conditions, then verify that the expected alert fires, routes correctly, and produces the full evidence artifact.
This approach separates validation from production traffic, so a misconfigured rule reveals itself during a planned test rather than during an audit window.
Synthetic event testing works rule by rule. For each correlation rule, document the exact log fields and values that should trigger it, then inject a crafted event into the pipeline and confirm the output. If the alert does not fire, the rule has a parsing or field-mapping error that silently eliminates coverage — precisely the failure mode an auditor cannot see but will expose when evaluating your evidence logs.
Tuning for false-positive reduction carries its own compliance risk. Suppressing an alert category to reduce noise can inadvertently remove coverage for a specific control objective. The discipline here is to document every suppression decision: record which rule was adjusted, which log source triggered the false positive, and which control the rule satisfies. That documentation proves to an auditor that coverage was narrowed deliberately and with awareness of the trade-off — not abandoned.
Regression testing should run on a defined schedule and after any pipeline change, including agent updates, parser modifications, or new log sources. Each test cycle should produce a pass or fail record per rule, stored alongside your other compliance artifacts. The implementation system in this guide structures this validation workflow so that coverage gaps surface automatically rather than accumulating silently between audit cycles.
Silent pipeline failures, such as clock skew between log sources or dropped events during ingestion, are far more dangerous to a compliance posture than noisy false positives because they leave evidentiary gaps that auditors will flag immediately.
Common Pipeline Failures That Invalidate Compliance Evidence
The most damaging SIEM pipeline failures are not the ones that produce false alerts — they are the ones that produce no alert at all, or produce evidence an auditor cannot trust. Four failure modes appear repeatedly in compliance assessments: clock skew between log sources, silent collection gaps during agent restarts, unencrypted log transport, and missing chain-of-custody records.
- Clock skew between log sources breaks sequence-dependent correlation rules and makes temporal evidence untrustworthy
- Silent collection gaps during agent restarts leave undetected windows where real incidents produce no record
- Unencrypted log transport exposes event data in transit and removes the auditor's ability to confirm integrity
- Missing chain-of-custody records prevent an auditor from confirming that a log archive is intact and unaltered
- Correlation rules that are never tested with synthetic events may silently fail to fire during real incidents
- Field-mapping errors introduced after a source update can cause events to bypass normalization without triggering a visible error
- Retention gaps caused by storage misconfiguration can delete log data before the compliance-mandated retention window closes
Each one can render an otherwise complete log archive inadmissible as compliance evidence, because the auditor cannot confirm that the record is intact, unaltered, and temporally accurate.
Clock skew is the most common and least visible problem. When different servers report events with timestamps that drift by even a few minutes, correlation rules that depend on event sequence break silently. An authentication failure followed by a privilege escalation looks unrelated if the timestamps diverge enough to fall outside the correlation window.
Auditors routinely check timestamp consistency across log samples, and unexplained divergence raises questions about log integrity that no after-the-fact explanation resolves.
Collection gaps during agent restarts are equally dangerous. If a log forwarding agent stops and resumes without buffering or acknowledgment, the events generated during that window disappear from the pipeline. The resulting gap in the log sequence is visible to an auditor as a suspicious absence — not as a technical oversight.
Unencrypted log transport creates a different problem: it leaves the chain of custody open to challenge, because an auditor cannot confirm that events were not modified in transit.
Detecting these failures before an audit window requires active monitoring of the pipeline itself — not just the events it carries.
SIEM Log Pipeline Stage Comparison: Detected vs Classified vs Routed
| Criterion | detected | classified | routed |
|---|---|---|---|
| Primary function | Identifies that a specific event occurred on the server | Assigns severity, category, and compliance context to event | Delivers qualified alert to responsible party within documented timeframe |
| Audit evidence produced | Timestamped raw event tied to a specific log source | Normalized record with severity label and rule reference | Alert receipt confirmation traceable to a requirement |
| Failure mode | Format fragmentation prevents matching events across sources | Volume without triage logic renders output meaningless to auditors | No documented destination or timeframe breaks audit trail |
| Framework linkage | Confirms event occurred within scoped log boundary | Maps event to specific control requirement by category | Demonstrates responsible-party accountability within required window |
| Input required | Raw log stream from OS, SSH, database, or application layer | Normalized event with consistent timestamp and field schema | Correlated alert meeting defined severity or rule threshold |
| Output destination | Correlation engine ingestion queue | Alert queue with rule-matched compliance tag attached | Ticketing system, notification channel, or auditor-ready log store |
The related guide Dedicated Server Audit Logging — Build a Stack explains how to organize normalized log data into evidence-ready records.
Conclusion – Turn Your Log Pipeline into a Continuous Audit Trail
A SIEM log pipeline earns its compliance value not at deployment but through continuous, documented operation. The sections above show that the architecture decisions you make early — normalized event formats, cryptographic log integrity, synchronized timestamps, and correlation rules mapped to specific control objectives — determine whether your log archive answers an auditor's questions or raises new ones.
Pipelines that reconstruct evidence before an audit are already failing; defensible compliance runs continuously or not at all.
Suppression decisions, regression test records, and gap-detection alerts are not operational housekeeping; they are the evidence that proves your coverage was deliberate and unbroken across every audit period.
The framework detailed throughout this guide gives your team a structured path from raw syslog output to an audit-ready evidence package: a normalized schema your auditor can navigate, correlation rules tied to named control requirements, integrity verification that survives chain-of-custody scrutiny, and a self-monitoring layer that surfaces pipeline failures before they become compliance gaps.
Each component builds on the last, so the result is a pipeline that produces defensible evidence continuously rather than scrambling to reconstruct it before an assessment window opens.




