Scaling a dedicated server feels straightforward until the invoice arrives. Most teams budget for the base monthly rate and assume the number stays stable — then discover that a hardware upgrade, a second node, or a single traffic surge can add costs that were never visible at signup. By the time the bill reflects reality, the budget cycle has already closed. The challenge is that dedicated server scaling costs follow three distinct triggers, and each one carries a different cost structure.
A vertical hardware upgrade — swapping in more RAM or moving to a higher-core processor — often involves a mid-contract reconfiguration fee on top of the new monthly rate. Adding a second node to distribute load introduces a separate billing line with its own bandwidth allotment and management tier. Traffic spikes, meanwhile, may be absorbed quietly by an unmetered port or billed aggressively through overage charges, depending entirely on how your contract handles burst capacity.
None of these scenarios is inherently expensive, but all three become expensive when they catch you unprepared. This article breaks down each scaling trigger as a distinct cost category, so you can forecast spend before a growth event forces your hand.
Why Dedicated Server Scaling Costs Are Hard to Predict
Dedicated server scaling costs are hard to predict because they rarely arrive as a single, clean line item. Instead, they surface as a cluster of simultaneous charges — each triggered by the same growth event but billed through different mechanisms, on different dates, and sometimes under different contract terms than your base agreement. The root cause is that static monthly pricing creates a false sense of cost certainty.
Your base rate covers a fixed hardware configuration under normal operating conditions. It does not account for what happens when that configuration changes. A mid-contract RAM upgrade, for example, may trigger a reconfiguration processing fee that does not appear in any pricing table at signup. That fee is separate from the new monthly rate, which itself may be calculated on a pro-rated basis for the remainder of your billing cycle — adding a partial-month charge on top of the upgrade cost.
Both charges land on the same invoice, and neither was visible when you signed.
The same logic applies across all three scaling triggers this guide addresses. Vertical hardware upgrades, additional nodes, and traffic spikes each carry their own billing logic, and that logic does not always align with your existing contract structure. A second server node introduces a new monthly line with its own bandwidth allotment, which may or may not pool with your existing allocation depending on how your agreement is written.
Traffic spikes interact with your bandwidth model — metered, unmetered, or 95th-percentile — in ways that only become visible when the overage charge appears. These triggers also compound: a traffic surge frequently precedes both a vertical upgrade and a node expansion, compressing the full budget impact into a single billing month and leaving little time to plan a measured response.
Mapping each trigger to its distinct cost structure in advance — before a growth event forces your hand — is the discipline this guide is built around. The sections that follow assign concrete cost logic to each trigger separately, then show how to consolidate all three into a single forecasting model you can maintain before capacity pressure arrives, not after it does.
That sequence matters: understanding what drives each charge, and when it lands, is what separates a scaling budget that holds from one that fails at the moment it is most needed.
Vertical upgrades, additional nodes, and sudden traffic surges each arrive with their own billing logic, making it essential to anticipate all three before any one of them forces an unplanned decision.
The Three Scaling Triggers That Drive Most Budget Overruns
Most dedicated server budget overruns trace back to three distinct triggers: vertical hardware upgrades, horizontal node expansion, and traffic spike absorption. Each trigger follows its own billing logic, arrives on its own timeline, and interacts with your existing contract in ways that are rarely obvious at signup. Treating them as a single undifferentiated “growth cost” is where forecasting breaks down.
A traffic spike may force a vertical upgrade mid-contract, which then exposes a storage ceiling that pushes you toward horizontal expansion — compressing three separate billing events into a single quarter. Understanding which trigger is actually driving a cost, and in what sequence, is the prerequisite for containing the damage before the invoice arrives.
What Does a Vertical Hardware Upgrade Actually Cost?
A vertical hardware upgrade costs more than the difference between your current plan tier and the next one. What a simple tier-to-tier comparison does not address is how the type of component being swapped changes the cost profile significantly.
A storage-tier migration can carry setup costs as large as provisioning an entirely new server.
RAM expansions tend to be simpler and cheaper to execute than CPU or storage swaps, which may require a full server migration to different physical hardware. When a storage upgrade means moving to a different chassis, the process can look operationally similar to provisioning a new server — with a comparable setup charge attached. That distinction matters for budgeting: a RAM upgrade and a storage-tier migration carry different cost profiles even if both appear on a quote as “hardware upgrade.”
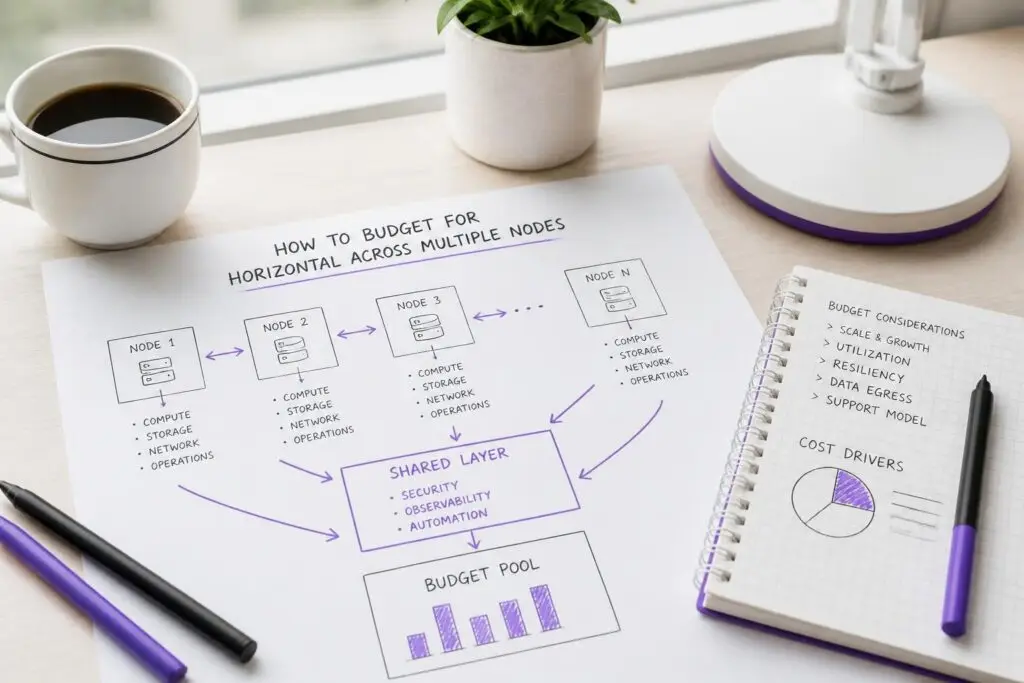
Every server added to a horizontal cluster brings its own recurring fees that stack in ways a simple per-unit estimate will consistently underestimate.
How to Budget for Horizontal Scaling Across Multiple Nodes
Horizontal scaling multiplies your base server cost, but that multiplication is rarely clean. Each additional node carries its own stack of recurring charges that compound in ways a simple "price times number of servers" calculation will not capture. The compounding begins with software licensing. A control panel license priced per server doubles when your node count doubles.
Commercial operating system distributions licensed per physical host add a recurring line item for every new node you provision. Database engine seats tied to host counts increase proportionally, and monitoring agent subscriptions billed per managed instance compound across even modest cluster expansions.
If your current single-server plan bundles some of these costs invisibly into a flat monthly fee, they surface as separate line items the moment you add a node on a different plan tier or in a different provider region. Auditing per-node licensing terms before you provision a second server is worth more to your budget than negotiating the base hardware price downward.
Inter-node bandwidth is the second charge that consistently catches teams off guard. Traffic flowing between application nodes and a dedicated database server, or between a primary and a replica, consumes bandwidth on each machine's allotment. Depending on whether your provider meters internal traffic separately from external egress, that internal communication can quietly erode your included bandwidth pool before any user-facing traffic is counted.
Some providers offer private network connectivity between co-located nodes at no additional cost; others bill it at standard egress rates. That single distinction can shift your monthly total meaningfully once you are running three or more nodes.
Per-node backup storage fees, private VLAN provisioning charges, and load balancer licensing fees that activate only once a second node exists are additional line items that rarely appear in a provider's headline pricing but appear reliably on your invoice.
Building a realistic horizontal scaling budget means constructing a per-node cost model that lists every recurring line item independently: hardware rental, control panel license, OS license tier, database seat, monitoring agent, backup allocation, and network interconnect. Once you have that per-node figure, multiply it across your projected node count at each growth stage — not just your current state.
A cluster that costs a manageable sum at two nodes can reach a materially different total at five if licensing and interconnect fees were excluded from the original model. Running that projection before a growth event, rather than during one, is the practical difference between a scaling budget that holds and one that requires emergency approval at the worst possible moment.
Traffic Spikes and Bandwidth Overages – Forecasting the Unpredictable
A traffic spike affects cost differently under each bandwidth model. A transfer-allotment plan may generate overage charges if total monthly transfer exceeds the allowance. An unmetered port generally does not add a usage charge but cannot exceed its contracted line rate. Under 95th-percentile billing, short bursts may be discarded, while sustained high utilization can increase the bill.
Use billing data that matches the contract model. For a monthly transfer allowance, compare total monthly transferred data with the included volume. For 95th-percentile billing, analyze the provider's sampling interval and sustained Mbps measurements. For an unmetered port, compare peak throughput with the contracted port speed.
Peak-to-average traffic ratio is the single most useful metric for sizing your bandwidth commitment before a spike forces an overage charge.
The case for a dedicated server with a fixed, unmetered bandwidth commitment becomes strongest precisely when your traffic is spiky but predictable in pattern. Elastic cloud alternatives can absorb unexpected volume, but their per-gigabyte overage rates often exceed what a dedicated plan with a larger committed port would have cost over the same period. Mapping your historical peak exposure against both billing models before a spike occurs is the step most teams skip.
How to Build a 12-to-36-Month Scaling Cost Forecast
A reliable scaling budget requires mapping your growth milestones to hardware and bandwidth thresholds across a multi-year horizon — not reacting to each threshold as it forces your hand. Teams that build this forecast in advance consistently spend less than those who approve emergency upgrades under operational pressure, because reactive decisions rarely allow for contract negotiation or timing optimization. Start by anchoring the forecast to your workload growth rate.
Teams that forecast scaling in advance usually avoid emergency upgrade premiums that appear when changes are approved under operational pressure.
If your compute demand has grown at a measurable pace over the past twelve months, project that trajectory forward in three stages: a conservative case, a base case, and an accelerated case. For each stage, identify the hardware threshold where your current configuration would begin to degrade — the point at which CPU saturation, RAM exhaustion, or storage limits become a real constraint.
Assign a cost range to each transition, drawing on the line items already established in your current plan: base hardware, management tier, licensing, backup allocation, and bandwidth commitment. The three-tier projection model prevents you from budgeting only for the expected scenario while leaving the accelerated case entirely unplanned. Next, build in a contingency buffer.
A practical approach is to reserve a percentage of your annual infrastructure budget specifically for unplanned scaling events — mid-contract hardware upgrades, emergency node additions, or bandwidth overage absorption. The right buffer size depends on how predictable your traffic patterns are; workloads with seasonal peaks or product-launch cycles warrant a larger reserve than stable, flat-growth environments.
Finally, revisit the forecast at each contract renewal point rather than treating it as a static document. Growth rates shift, hardware generations change the cost-per-core equation, and provider pricing evolves.
Certain cost categories appear so rarely in pre-sales quotes that most teams only discover them when the invoice lands, often at the worst possible moment in a growth cycle.
Which Scaling Costs Are Often Overlooked Until the Invoice Arrives?
What matters here is which specific categories are most consistently absent from pre-sales quotes — and why their timing makes them particularly damaging to a budget.
Additional IP addresses may be required for network separation, legacy applications, customer isolation, or services that cannot share an address. Modern HTTPS hosting normally supports multiple certificates on one IP address through Server Name Indication, so SSL certificates alone should not be used to estimate the required address count.
Similarly, managed support tier overruns catch teams off guard: a plan that includes a fixed number of support hours per month may treat a migration or configuration change triggered by a scaling event as billable hours above the included allowance. The same logic applies to control panel licensing, where seat-based or per-server pricing means that adding a node automatically adds a licensing fee that was not visible in the original plan quote.
Adding a node or region can change the scope of a PCI DSS environment. Review the change with the organization's compliance owner or assessor and update network diagrams, inventories, segmentation evidence, scans, and other validation activities where required. Do not assume that every scaling event automatically requires a complete new audit.
- Per-IP-address or IP block fees triggered automatically when new nodes are added to a cluster
- Managed support tier overruns when a scaling event consumes more than the plan's monthly included hours
- Control panel license charges that activate per additional server rather than per account
- Backup storage expansion fees when a larger disk or additional node pushes snapshot volume beyond the included allotment
- SSL certificate provisioning or reissuance costs tied to new hostnames or dedicated IPs
- Compliance or audit log retention fees that scale with the number of managed instances
- Out-of-band or IPMI access charges added when remote management is needed during a hardware migration
Managed vs. Unmanaged Plans – How the Support Model Shifts Your Scaling Economics
The choice between managed and unmanaged dedicated infrastructure directly changes what a scaling event costs in total — not just in hardware, but in staff time, response speed, and operational risk. On an unmanaged plan, your team owns every step of the upgrade process: kernel tuning, OS reconfiguration, firewall rule updates, and service migration. On a managed plan, the provider absorbs much of that labor.
The critical decision rule is whether your team can absorb that labor under pressure, not under normal conditions. A vertical hardware migration that takes an experienced infrastructure engineer two to four hours can consume an entire sprint for a small development team handling it alongside other responsibilities.
Managed plans price that labor into the monthly fee, making the headline cost appear higher; unmanaged plans defer it to the moments when it is most expensive to absorb.
The break-even point depends heavily on your team's size and existing infrastructure expertise. The risk profile also differs at the moment of a traffic spike or node expansion. A managed provider can execute a configuration change or failover procedure within a defined SLA window. An unmanaged environment places that response entirely on your internal team, often outside business hours.
For regulated industries, that response gap can carry compliance implications beyond the immediate cost.
The financial crises that follow scaling events are almost always rooted in planning gaps that were present long before growth exposed them.
Four Budgeting Mistakes That Turn Scaling Events Into Financial Emergencies
Most dedicated server scaling emergencies are not caused by unexpected growth — they are caused by predictable planning gaps that compound quietly until a growth event makes them visible.
Two or three upgrade cycles over two years is common, yet most budgets only account for one.
What the three-trigger cost model does not automatically reveal is where execution breaks down. Four specific mistakes account for the majority of overruns, and each carries a corrective principle teams can apply before signing any infrastructure commitment — starting with the contracts already in place, not just the ones being considered.
Teams often model one hardware upgrade over a two-year horizon when their actual workload trajectory demands two or three. Each upgrade carries not just a plan-tier cost difference but also associated fees for migration, reconfiguration, and potential downtime. Budgeting for a single event when the pattern is cyclical leaves a structural gap in every forecast.
The corrective principle is to model upgrade intervals based on your historical resource consumption rate, not on the assumption that your current tier will hold. The second mistake is ignoring contract penalty clauses.
Early-termination fees and minimum-commitment obligations can add a significant lump sum to a scaling decision if you need to exit a plan before the contract period ends. Dedicated Server Contract Terms – What to Check Before You Sign covers this cost layer in detail, but the planning principle here is straightforward: read the exit terms before you enter, not when growth forces a change. The third mistake is conflating promotional pricing with renewal rates.
A plan priced attractively at signup can renew at a materially higher rate, which distorts any multi-year cost model built on the introductory figure. Dedicated Server Hosting Pricing – What You Actually Pay addresses this gap directly. The fourth mistake is failing to model peak-load bandwidth consumption separately from average monthly usage. Overage charges accumulate at peak moments, not at average ones — and averages mask the spikes that drive invoices.
Conclusion – Build Your Scaling Budget Before Growth Forces Your Hand
Scaling a dedicated server environment becomes financially manageable the moment you treat it as a predictable sequence of events rather than a series of emergencies. The three cost triggers — vertical hardware upgrades, additional nodes, and traffic spikes — each carry distinct billing mechanics. Mapping them to your workload trajectory before a growth event occurs is what separates teams that absorb scaling costs smoothly from those that absorb them painfully.